Technical Deep Dive

Glass — Under the Hood

The programming languages, frameworks, databases, and infrastructure that power the Glass platform. This is the technical detail — for the sales overview, see the main Glass page.

Under the hood

The full stack

Languages & Frameworks

PHP 8.3Slim 4Symfony / PlatformGo 1.25Chi Python 3.11FastAPIPydantic v2 TypeScriptJavaScriptReact 18ViteSQL

Data & AI

PostgreSQL 16pgvectorRedis 7 Ollamaglass-devdeepseek-r1:70bWhisperPyannote Diarization Redis StreamsJSONB

Infra & DevOps

Docker ComposeNginxmTLSBrotli Cloudflare TunnelTailscaleCalVer

Security & Ops

Wazuh SIEMGlass Strix PentestRustDesk OSSMeshCentral RspamdClamAV OIDC / AuthentikMFALokiGrafana
Polyglot Architecture

Every service, every language

Each service picks the right language for the job — PHP for domain logic, Go for high-throughput, Python for AI pipelines.

ServiceLanguage / FrameworkWhat It Does
CRU-GlassPHP 8.3 · Vite · ES6Core monolith — 11 dashboards, ticket UI, admin, AI report builder, 3D facility viewer
glass-corePHP 8.3 · Slim 4 · JWT RS256Auth & identity — SSO/OIDC, MFA, 7-tier RBAC, settings manager
glass-ticketsPHP 8.3 · Slim 4PSA/ITSM — lifecycle state machine, rules engine, time tracking
glass-tickets-sla-goGo 1.25 daemonSLA sidecar daemon — high-frequency deadline tracking and alert triggers
glass-assetsPHP 8.3 · Slim 4CMDB — asset lifecycle, dynamic health scoring, warranties, RMA tracking
glass-cyberPHP 8.3 · Slim 4 · PostgreSQL JSONBCybersecurity awareness training & testing — interactive modules & quizzes, phishing simulations, risk scoring
glass-rmmGo 1.25 · RustDesk + MeshCentralRMM & dual remote access — remote shell, auto-checkin tokens, interactive terminal, patch deployment
glass-invoicePHP 8.3 · Symfony / PlatformNative billing engine (SolidInvoice) — invoices, recurring subscriptions, quotes, payment gateways (replaces QBO)
glass-unifiGo 1.25 + PythonTelephony & audio — UniFi Talk, Android Call & Meeting Audio Pipeline (Whisper ASR + Pyannote diarization)
glass-chatGo 1.25 · WebSocket · React 18Real-time messaging — WebRTC voice/video, call transcription (10k+ concurrent connections)
glass-superopsPHP 8.3 · PostgreSQLPSA sync & native replacement — retired in production at Sterling Innovations (110x speedup: 30.5 ms search)
glass-procurementPHP 8.3 · Slim 4Procurement — purchase-order lifecycle, supplier catalog, automated totals
glass-feedbackPHP 8.3 · Slim 4Bug tracking — AI developer-prompt generation, threaded notes
glass-crmGo 1.25 · Chi · React SPACRM — campaigns, Redis Streams, SKIP LOCKED queue dispatch
glass-sentinelGo 1.25 · ChiXDR & security ops — Wazuh SIEM on DMZ, multi-tenant isolation, blocklists, posture & sandboxed remediation
glass-strixPython / DockerAutomated penetration testing — vulnerability scanning, attack simulation, and CVE mapping
glass-odysseusPython 3.11 · FastAPI · MCPSilica (AI) Workspace — Chat, Deep Research, Document Library, and live Glass MCP tool execution
glass-ai-workerPython 3.11 · FastAPI · PydanticMulti-Provider AI Router — DGX Spark (ollama), Secondary Local GPU (ollama_local), Gemini, Claude, OpenAI, AI_BACKUP_CHAIN failover, Dual-LLM sandbox & pgvector RAG
glass-ai-benchyPython 3.11 · FastAPI · ReactAI Benchmark & 6-Stack Optimizer — evaluates local & cloud models across DEV, HEAVY, THINK, OPS, VISION, and EMBED stacks
glass-emailPHP 8.3 · Slim 4 · EWSEmail — Exchange ingestion, AI triage & noise scoring

Highlighted rows = Go / Python (non-PHP)

Self-Hosted · Requirements

The hardware to run Glass

Glass runs on your own hardware — the Docker platform (40+ containers) plus AI inference. And you choose how the AI runs: host it locally on a GPU for full data sovereignty, or point it at a frontier-model subscription and skip the GPU entirely.

Option 1 · Dual-Node Self-Hosted AI (DGX Spark + Local GPU)

Run Ollama on your primary NVIDIA DGX Spark (128GB unified) and/or a secondary Local Workstation GPU (ollama_local). Route lightweight fast-lane triage to your local GPU while heavy reasoning stays resident on the Spark — with 100% data sovereignty.

Option 2 · Frontier APIs & Ordered Backup Failover Chain

Configure an ordered Backup Failover Chain (AI_BACKUP_CHAIN) across ollama_local, Google Gemini (2.5-pro, 2.5-flash), Anthropic Claude, OpenAI, or any OpenAI-Compatible API (vLLM, LiteLLM, Groq). Use cloud APIs as your primary engine or as zero-downtime automatic failover.
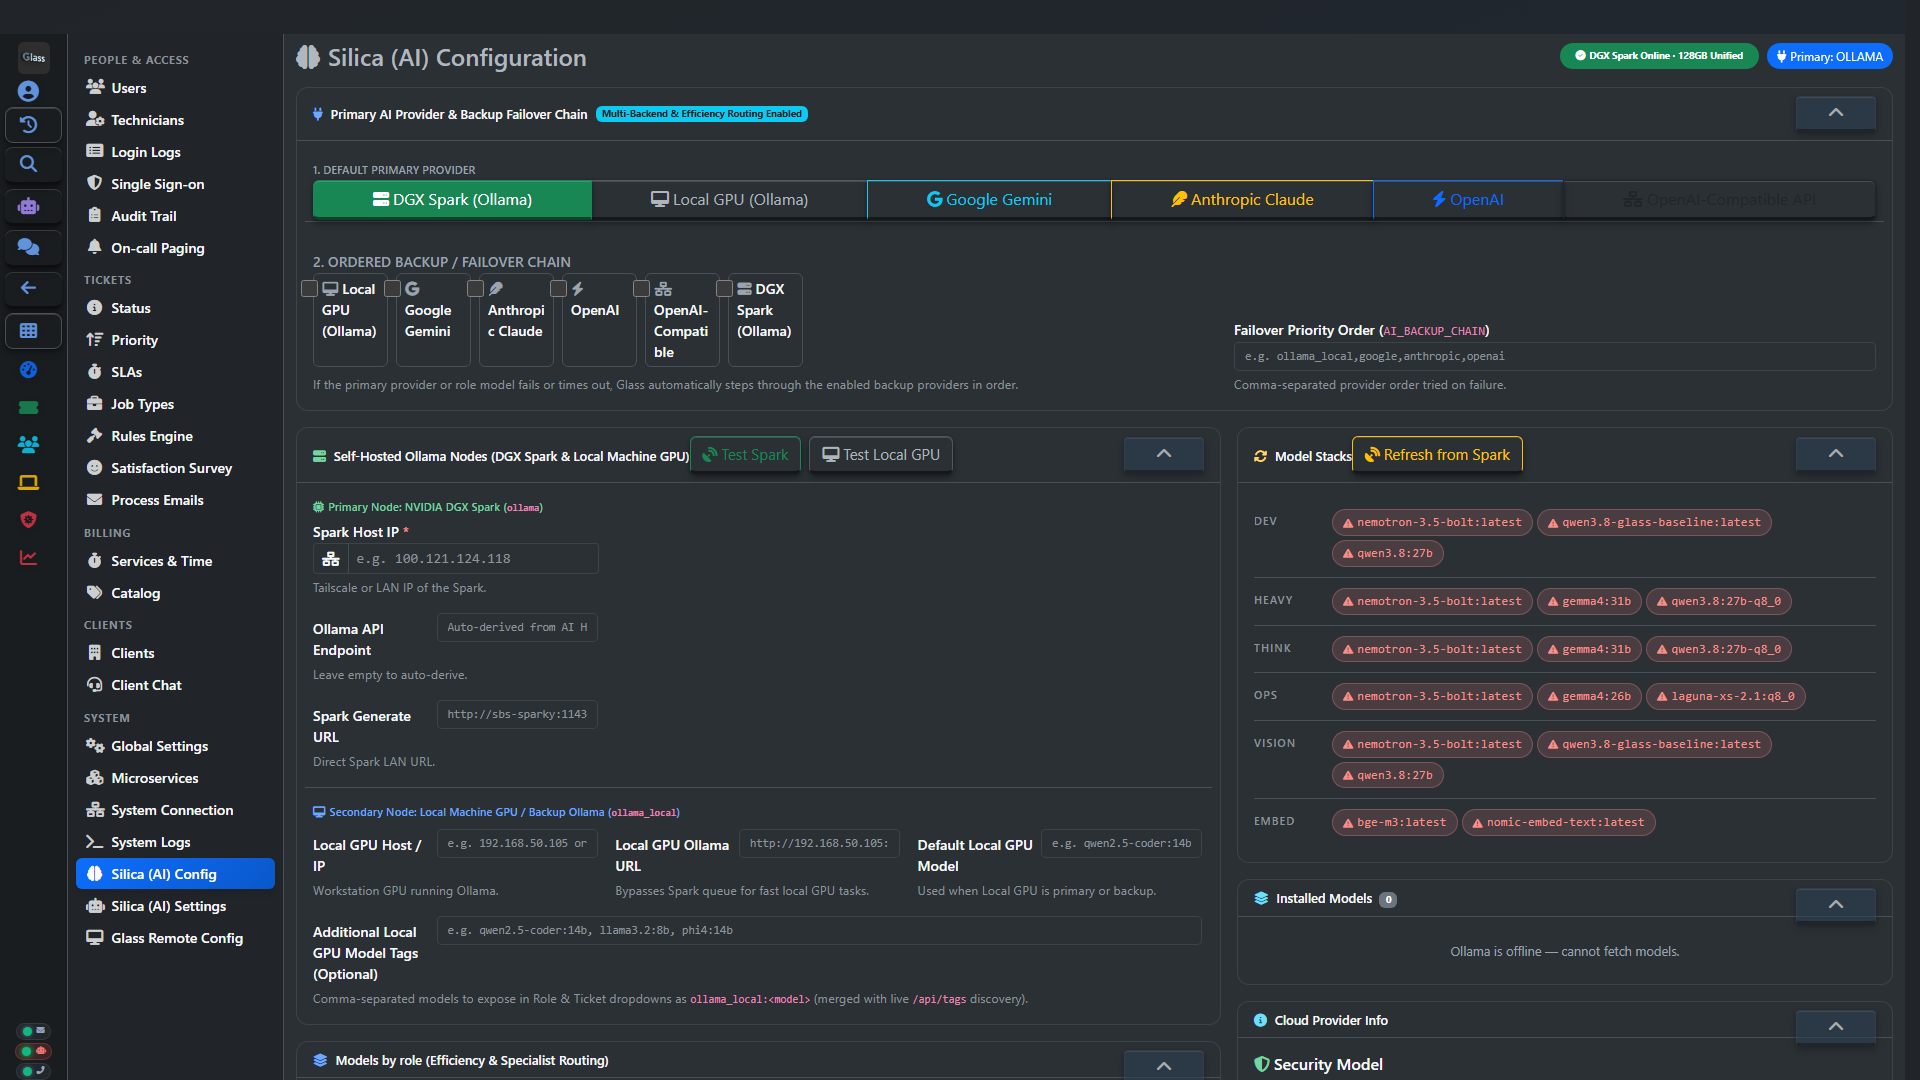
glass.internal / index.php?page=admin&tab=ai_config · Live Multi-Provider Silica (AI) Configuration
Live screenshot of Glass Admin Silica (AI) Configuration showing Primary Provider, Ordered Backup Failover Chain, DGX Spark + Secondary Local GPU nodes, and 6-Stack Optimizer
WorkloadMinimumRecommendedWhat CRU runs
Docker platform (no AI)8 cores · 16 GB · 256 GB SSD16 cores · 32 GB · 512 GB NVMe80 cores · 512 GB
AI inference (Ollama)16 GB VRAM / 32 GB unified48–64 GB VRAM / unified128 GB unified (Blackwell)
Combined (one machine)16 cores · 64 GB · GPU32 cores · 128 GB · GPUDGX Spark + Server stack

Budget build

~$2,000–3,000
  • Mini PC / NUC — i7 or Ryzen 7, 32 GB RAM, 1 TB NVMe
  • Used RTX 3090/4090 (24 GB VRAM)
  • 600VA UPS

Runs the full platform; AI swaps models between requests. No deep reasoning.

Recommended build

~$5,000–8,000
  • Server — 16 cores, 64 GB ECC, 2 TB NVMe
  • RTX A6000 (48 GB) or L40
  • 1500VA UPS

Full Dual-LLM + all AI features (except deep reasoning). Best for 5–10 techs.

Premium build

~$10,000–15,000
  • NVIDIA DGX Spark — 128 GB unified Blackwell
  • Dedicated app server (16+ cores, 32+ GB)
  • NAS backup + 2000VA UPS

Everything — all models resident, deep reasoning, headroom for future models. CRU's setup.

The GPU is only for self-hosted AI. Choose the frontier-model subscription instead and the Budget/Recommended builds drop the GPU entirely — Glass then runs on a modest CPU-only server. Docker Compose profiles let you deploy only the services you need.

Want the sales overview instead?

This page is for engineers who want the nitty-gritty. For the business case, feature comparison, and licensing — head back to the main pages.